
Based on: NCERT Statistics for Economics, Chapter 8 (Reprint 2026-27), Appendices A and B, and the Project Work guidelines of the CBSE 2026-27 curriculum. In CBSE this chapter is not a separate topic of the theory paper; it prepares you for the 20-mark project work. The UP, Bihar, Rajasthan and MP boards teach from the same book.
- The seven steps of a project, from identifying the problem to the bibliography
- How to choose a target group, when to use primary or secondary data, and how to frame a questionnaire
- The book’s toothpaste sample project: questionnaire, tables, diagrams and observations
- Solving the mean (assumed-mean / step-deviation method), median, mode, ogives and pie-diagram angles on that survey
- The book’s 12 suggested projects and the CBSE project marking scheme
- The key terms of Appendix A and the use of the random numbers in Appendix B
1 Introduction: what statistical tools are for
In this book you have learnt to collect data, organise it, draw diagrams, find averages, correlation and index numbers. These tools are useful in daily life and in analysing data on economic activities.
Economic activities
Analysis of data on production, consumption, distribution, banking and insurance, trade and transport
The book’s examples
Information about a product from the consumer, a new product or service to be launched in the market, the spread of information technology in schools
Why a project
Conducting a survey and preparing a report helps analyse the information and suggest improvements in a product or system
Statistics: the method of collecting, organising, presenting and analysing data to draw meaningful conclusion. Further, it also means data. (Appendix A)
A project = picking an economic question, collecting data (your own or secondary), using all the statistical tools of this book together, and writing a conclusion.
this chapter in one sentence
2 Steps towards making a project
The book gives seven steps for making a project. Learn them in this order; the order can be asked.
“People Take Coffee Over Afternoon Coffee Breaks”
Problem → Target group → Collection → Organisation and presentation → Analysis → Conclusion → Bibliography.
2.1 Identifying a problem or an area of study
- At the outset you should be clear about what you want to study (the objective)
- On the basis of the objective you proceed with the collection and processing of the data
- The book’s examples: production or sale of a product like a car, mobile phone, shoe polish, bathing soap or a detergent
- Water or electricity problems of households of a particular area
- Consumer awareness among households, i.e. awareness about the rights of consumers
2.2 Choice of target group
The target group is the set of persons on whom you focus your attention and from whom you collect information. Choosing it is important for framing appropriate questions for the questionnaire.
| Project on | Target group (the book) | Why |
|---|---|---|
| Cars | Mainly the middle income and the higher income groups | They are the buyers of cars |
| Consumer products like soap | All rural and urban consumers | Almost every household buys soap |
| Availability of safe drinking water | Both urban and rural population | The problem exists in both |
2.3 Collection of data
The objective of the survey decides whether data collection uses the primary method, the secondary method or both.
Primary data are data collected first hand by the investigator, with the help of a questionnaire or an interview schedule.
Secondary data are data already collected and published by someone else, which the investigator uses in his study.
Primary data (the book’s points)
- Collected with a questionnaire or an interview schedule
- Through personal interviews, mailing/postal surveys, phone, email
- A postal questionnaire must have a covering letter giving details about the purpose of the inquiry
- For a study of female literacy or consumption of a brand of soap you must go to every household
Secondary data (the book’s points)
- Can be used provided they suit your requirement
- Usually used when there is paucity of time, money and manpower resources
- and the information is easily available
- Their sources are listed in the bibliography
- Your objective determines the size and characteristics of the target group
- If sampling is used in data collection, care has to be taken about the suitability of the method of sampling
Questionnaire: a list of questions prepared by an investigator on the subject of enquiry. The respondent is required to answer the questions. (Appendix A)
Structured questionnaire: consists of “closed-ended” questions, for which alternative possible answers to choose from are provided. (Appendix A)
| Basis | Questionnaire | Interview schedule |
|---|---|---|
| Filled in by | The respondent himself (e.g. one sent by post) | The enumerator, who asks the respondent |
| Goes with | A covering letter, if postal | A personal interview |
| Useful when | Respondents are literate and far away | Questions need to be explained |
2.4 Organisation and presentation of data
- After collection, the information received has to be processed
- By tabulation and suitable diagrams: bar diagrams, pie diagrams, etc. (chapters 3 and 4)
- A histogram and ogives for a frequency distribution with continuous classes; a time-series graph for data over time
2.5 Analysis and interpretation
| Tool (the book) | Example | What it tells |
|---|---|---|
| Measures of central tendency | Mean (also median, mode) | The average |
| Measures of dispersion | Standard deviation | Variability (how far the data spread from the average) |
| Correlation | Karl Pearson’s r, Spearman’s rank correlation | The relationship among variables, if it exists |
The book says you have learnt these measures in chapters 5 and 6. After analysis, every result needs an interpretation: the meaning of the number in one sentence.
2.6 Conclusion
- The last step: draw meaningful conclusions after analysing and interpreting the results
- If possible, try to predict the future prospects on the basis of the information collected
- Give suggestions relating to growth and government policies
2.7 Bibliography
This section mentions the details of all the secondary sources used for developing the project: magazines, newspapers, research reports.
The bibliography does not list the respondents of your survey. It lists only secondary sources. And the conclusion is not a repeat of the summary; it gives findings, future prospects and suggestions.
3 CBSE project work: guidelines and marks
CBSE Class 11 has an 80-mark theory paper and 20 marks of project work (Part C). This chapter prepares you for it. The points below are from “Guidelines for Project Work in Economics” in the CBSE 2026-27 curriculum.
- Probe deeper into theoretical concepts learnt in classes XI and XII
- Analyse and evaluate real world economic scenarios using theoretical constructs and arguments
- Demonstrate the learning of economic theory
- Follow up aspects of economics in which learners have interest
- Develop the communication skills to argue logically
The project is an independent, self-directed piece of study.
| Heading | Marks |
|---|---|
| Relevance of the topic | 3 |
| Knowledge content/research work | 6 |
| Presentation technique | 3 |
| Viva-voce | 8 |
| Total | 20 |
- Introduction of topic/title
- Identifying the causes, consequences and/or remedies
- Various stakeholders and the effect on each of them
- Advantages and disadvantages of situations or issues identified
- Short-term and long-term implications of the economic strategies suggested
- Validity, reliability, appropriateness and relevance of the data used
- Succinct and coherent presentation and writing
- Citation of the materials referred to (footnotes, resources section, bibliography)
- Role of the teacher: help select the topic from news extracts, government policies, the RBI bulletin, NITI Aayog and IMF/World Bank reports; supervise through periodic discussions; guide on sources of data; teach about plagiarism and quoting sources
- Presentation: at the end of the term the project file is presented to the internal and external examiners; questions are asked from the file; the work must be the learner’s own original work
- Suggested Class 11 topics (CBSE): effect on PPC due to government policies; opportunity cost as an economic tool; effect on equilibrium prices in the local market; solar energy compared with conventional sources; invisible hand (Adam Smith); effect of a price change on a substitute or complementary good (from the local market); bumper production, boon or bane for the farmer; any newspaper article evaluated on economic principles
4 Suggested list of projects (the book’s 12)
The book says you are free to choose any topic that deals with an economic issue. In each suggested project you play a role.
| No. | Your role | Project topic | Main data and tools (suggestion) |
|---|---|---|---|
| 1 | Advisor to the Transport Minister | A better and coordinated system of transportation | Mode, time, fare; pie diagram, mean |
| 2 | Working in a village cottage industry (dhoop, agarbatti, candles, jute products) | Project proposal for a bank loan for your own new unit | Cost, sales, profit tables; secondary market data |
| 3 | Marketing manager in a company | Effect of advertisements on the sale of your product | Advertising spend and sales; correlation |
| 4 | District Education Officer | Literacy levels and reasons for children dropping out of school | Literacy rate, table of reasons; bar diagram |
| 5 | Vigilance Officer | Overcharging above the Maximum Retail Price (MRP); visit a few shops | MRP and price charged; percentages |
| 6 | Head of a Gram Panchayat | Amenities like safe drinking water | Water source, distance; pie diagram |
| 7 | Representative of a local government | Participation of women in employment schemes | Percentage of women by scheme; multiple bar diagram |
| 8 | Chief Health Officer of a rural block | Health and sanitation problems | Illness, toilets, clean water; tables |
| 9 | Chief Inspector of Food and Civil Supplies | Food adulteration; a survey of the magnitude of the problem | Percentage of adulterated samples |
| 10 | (in a particular area) | Report on the Polio immunisation programme | Children immunised by age; percentages |
| 11 | Bank Officer | Saving habits, taking income and expenditure into account | Income and saving; mean, correlation |
| 12 | Group of students | Farming practices and the problems facing farmers in a village | Land, crops, income, credit; tables, mean |
5 Sample project: a toothpaste factory
The book gives a sample project for guidance. Depending on your subject the method will be different. The situation: X is a young entrepreneur who wants to set up a factory to produce toothpaste. You are asked to advise X about how he should proceed.
- First, study people’s tastes with regard to toothpastes, their monthly expenses on toothpaste and other relevant facts
- For this you decide to collect primary data, with the help of a questionnaire
- The questionnaire must be capable of generating all the information you need
- A questionnaire already tried out and tested (perhaps for a similar study) can be used after suitably modifying it; otherwise prepare it yourself
Average monthly expenditure
on toothpaste
Brands in demand
currently
Attitude
of customers towards these brands
Ingredients
customers’ preferences in the toothpaste
Media influences
on consumers’ demand for toothpaste
Income
the relation between income and all the above factors
5.1 Example of questionnaire (the book’s 15 questions)
| Question | What is asked | Type |
|---|---|---|
| 1-5 | Name, sex, ages of family members, total number of members, monthly family income | Personal/family details |
| 6 | Location of residence: urban / rural | Closed (two options) |
| 7 | Major occupation of the main bread-winner: service, professional, manufacturer, trader, any other | Multiple choice |
| 8 | Does your family use toothpaste to clean your teeth? Yes / No | Closed (yes/no) |
| 9 | Essential qualities of a good toothpaste: plain, gel, antiseptic, flavoured, caries protection, fluoride, other (tick more than one) | Multiple response |
| 10-11 | Which brand; how many 100 gram packs per month | Open/numerical |
| 12-13 | Satisfied with this toothpaste? Prepared to try a new toothpaste? Yes / No | Closed |
| 14 | Features you would like in the new toothpaste (more than one) | Multiple response |
| 15 | Main sources of information: cinema, exhibitions, internet, magazines, newspapers, radio, sales representatives, television, other | Multiple response |
If asked what makes a good questionnaire, take examples from this one: short, simple questions; mostly closed questions (yes/no, options) so answers can be counted into tables; a logical order (family details first, then the product); and an “any other (please specify)” option.
6 Data analysis and interpretation: simplified project report
After collecting the information you organise and analyse it. The book’s final report follows. Each table is followed by an observation: that is the interpretation.
Observation: majority of users belonged to the urban area.
6.1 Age distribution
| Age in years | Below 10 | 10-20 | 20-30 | 30-40 | 40-50 | Above 50 | Total |
|---|---|---|---|---|---|---|---|
| No. of persons | 74 | 56 | 91 | 146 | 93 | 40 | 500 |

Observation: majority of the persons surveyed belonged to the age group 20-50 years: 91 + 146 + 93 = 330, i.e. 66% of 500.
The sample is 100 households, but the age table counts 500 persons, because the ages of all family members were asked (question 3). Write the unit carefully.
6.2 Family size
| Family size | 1-2 | 3-4 | 5-6 | Above 6 | Total |
|---|---|---|---|---|---|
| No. of families | 20 | 40 | 30 | 10 | 100 |
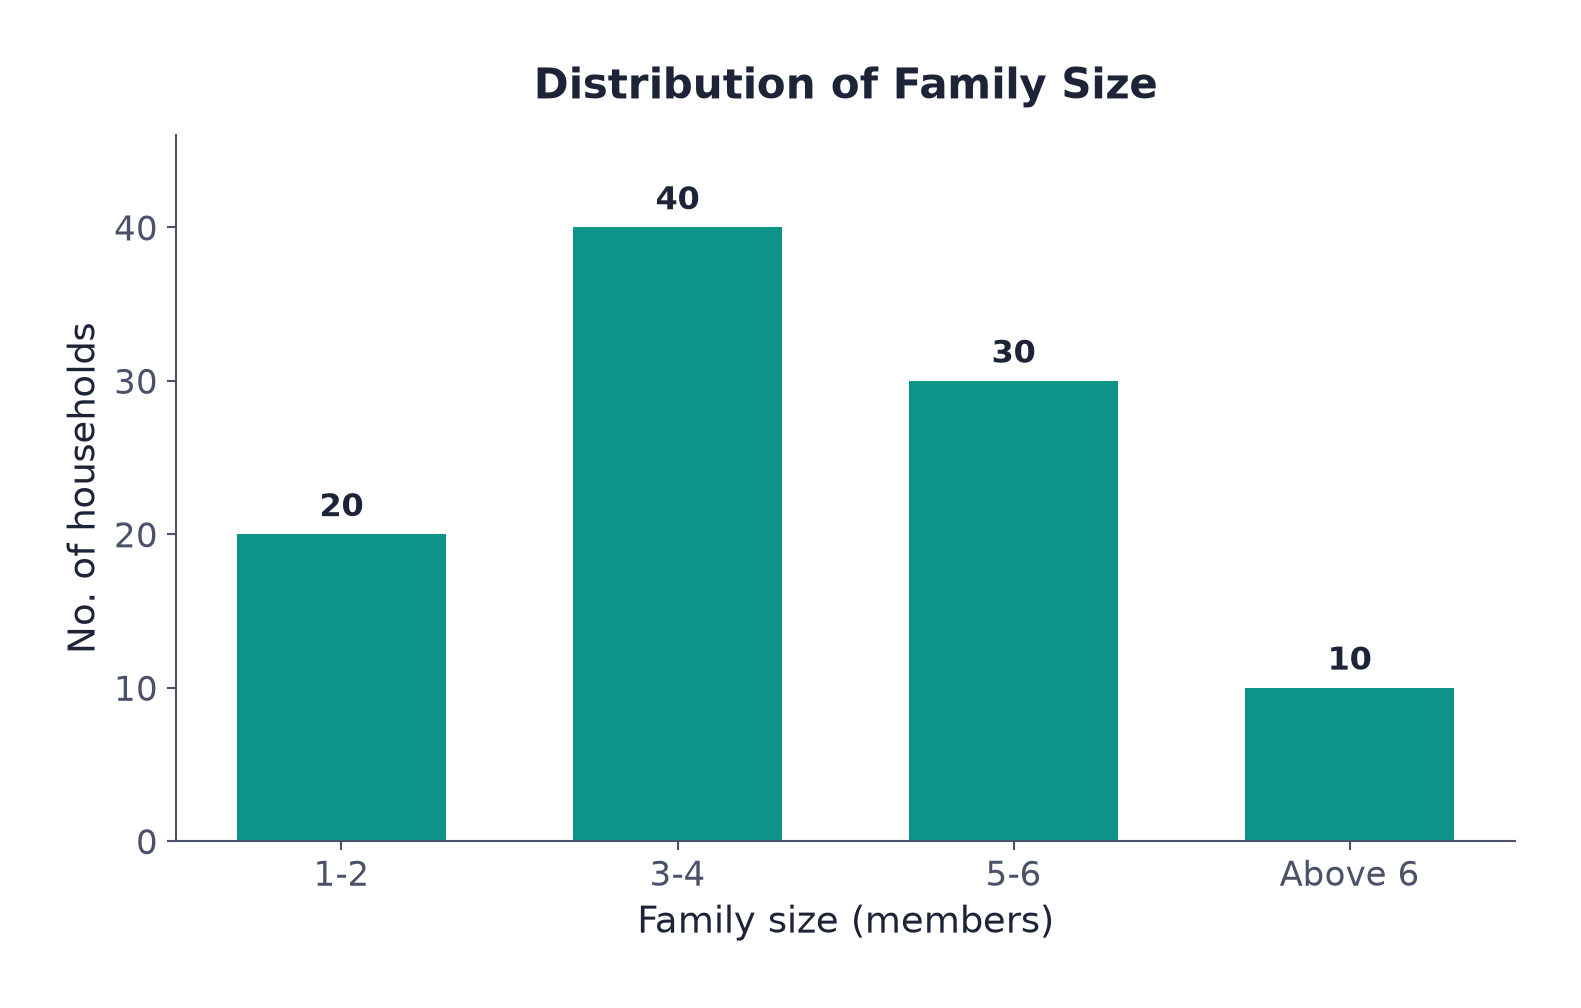
Observation: majority of the families surveyed have 3-6 members (40 + 30 = 70 families).
6.3 Monthly family income status: mean by the step-deviation method
| Income class (₹) | Midpoint | Frequency | |||
|---|---|---|---|---|---|
| 0-10000 | 5000 | 20 | −3 | −60 | 180 |
| 10000-20000 | 15000 | 40 | −1 | −40 | 40 |
| 20000-30000 | 25000 | 30 | 1 | 30 | 30 |
| 30000-40000 | 35000 | 10 | 3 | 30 | 90 |
| Total | Σf = 100 | Σfd′ = −40 | Σfd′² = 340 |
Given
, , ,
To find
Mean monthly income
Formula: (½)
Substitution: (½)
Answer: mean monthly income = ₹18,000 (1)
Interpretation: an average surveyed family earns ₹18,000 a month.
is 20,000, not 2,000. And is negative (−40), so the mean comes out below . Dropping the sign gives a wrong 22,000.
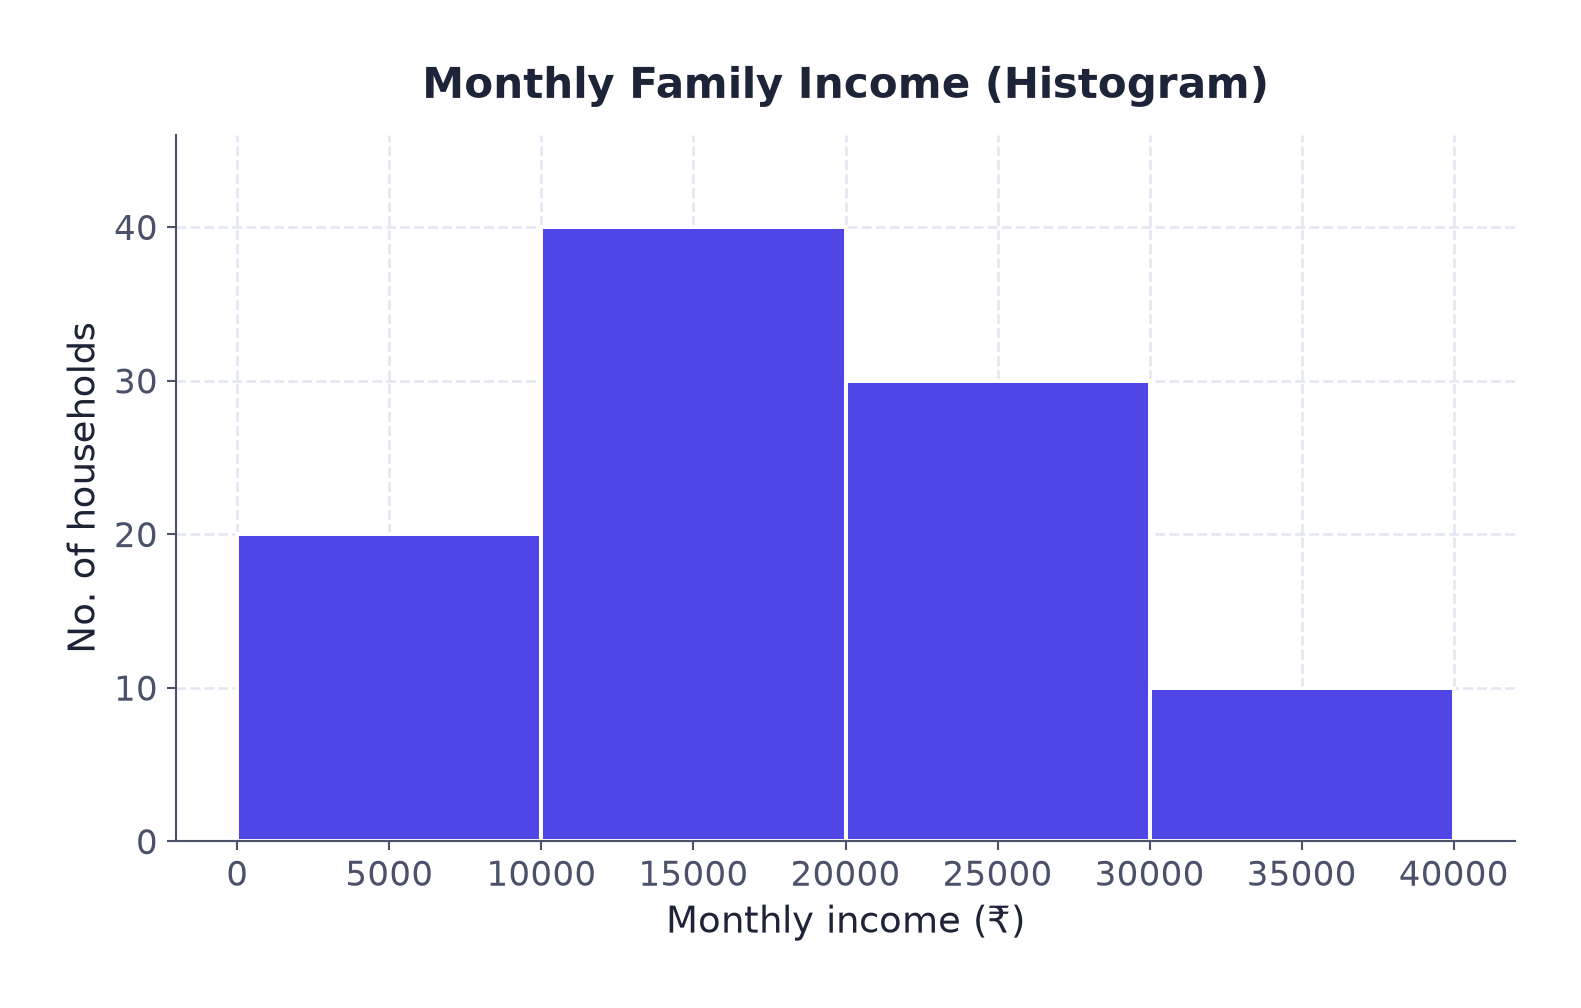
Observation: majority of the families surveyed have monthly income between ₹10,000 and ₹30,000 (40 + 30 = 70 families).
As a “measure of dispersion” the book also finds the standard deviation () in this project. It tells how far incomes spread from their mean on average. Dispersion is not in the CBSE syllabus; the formula is given only for reading:
For income: ₹9,000
Interpretation: the mean income was ₹18,000 and the standard deviation ₹9,000; incomes differ widely between families.
6.4 Monthly family budget on toothpaste
| Monthly expenditure class (₹) | Midpoint | Frequency | |||
|---|---|---|---|---|---|
| 0-40 | 20 | 5 | −2 | −10 | 20 |
| 40-80 | 60 | 20 | −1 | −20 | 20 |
| 80-120 | 100 | 40 | 0 | 0 | 0 |
| 120-160 | 140 | 30 | 1 | 30 | 30 |
| 160-200 | 180 | 5 | 2 | 10 | 20 |
| Total | 100 | 10 | 90 |
Given: , , ,
Formula: (½)
Substitution: (½)
Answer: mean monthly expenditure on toothpaste per household = ₹104 (1)
Standard deviation (not in syllabus): ₹37.74
Interpretation: an average household spends about ₹104 a month on toothpaste.
Do not forget the square root: , not 0.89. Take from the total of column (6); each row is , not .
6.5 Major occupational status: pie diagram
| Family occupation | No. of families | Per cent | Angle |
|---|---|---|---|
| Service | 30 | 30% | 30/100 × 360° = 108° |
| Professional | 5 | 5% | 18° |
| Manufacture | 10 | 10% | 36° |
| Trader | 40 | 40% | 144° |
| Any other (please specify) | 15 | 15% | 54° |
| Total | 100 | 100% | 360° |

Observation: majority of the families surveyed were either service class or traders (30 + 40 = 70).
6.6 Preferred use of toothpaste (brands)
| Brand | No. of households | Brand | No. of households |
|---|---|---|---|
| Aquafresh | 5 | Anchor | 4 |
| Cibaca | 9 | Babool | 3 |
| Close-up | 12 | Promise | 3 |
| Colgate | 18 | Meswak | 5 |
| Pepsodent | 20 | OralB | 7 |
| Pearl | 4 | Sensodyne | 7 |
| Any other | 3 | Total | 100 |

Observation: Pepsodent, Colgate and Close-up were the most preferred brands; together 50 households.
6.7 Basis of selection
Observation: majority of the people selected the toothpaste on the basis of standardised markings, quality, price and the company’s brand name.
These figures add up to 225, not 100, because a family could tick more than one basis (a multiple-response question). Such data cannot be shown by a pie diagram, since the parts do not make one whole; use a bar diagram. The same holds for ingredients (total 280) and media (total 165).
6.8 Taste and preferences (satisfaction)
| Brand | Satisfied | Unsatisfied | Total users | Dissatisfaction % |
|---|---|---|---|---|
| Pepsodent | 18 | 2 | 20 | 10.0% |
| Colgate | 16 | 2 | 18 | 11.1% |
| Close up | 10 | 2 | 12 | 16.7% |
| Cibaca | 5 | 4 | 9 | 44.4% |
| OralB | 4 | 3 | 7 | 42.9% |
| Sensodyne | 5 | 2 | 7 | 28.6% |
| Aquafresh | 2 | 3 | 5 | 60.0% |
| Meswak | 3 | 2 | 5 | 40.0% |
| Anchor | 2 | 2 | 4 | 50.0% |
| Pearl | 2 | 2 | 4 | 50.0% |
| Babool | 2 | 1 | 3 | 33.3% |
| Promise | 2 | 1 | 3 | 33.3% |
Dissatisfaction % = unsatisfied ÷ (satisfied + unsatisfied) × 100. Each brand’s total users match the brand table in 6.6 exactly.
Observation: amongst the most used toothpastes the percentage of dissatisfaction was relatively less (Pepsodent 10%, Colgate 11.1%).
6.9 Ingredients preference
Observation: majority of the people preferred gel and antiseptic-based toothpastes over the others.
6.10 Media influence

Observation: majority of people came to know about the product either through television (47) or through newspaper (30).
6.11 Concluding note of the project report
- Majority of the users belonged to the urban area
- Most of the people surveyed belonged to the age group 20-50 years and had on average 3-6 members in a family
- The monthly income of these families ranged between ₹10,000 and ₹30,000 and their main occupations were service and trading
- Expenditure on toothpaste accounted for about ₹104 per month per household
- Pepsodent, Colgate and Close-up were the most preferred brands in the households surveyed
- People preferred brands of toothpaste which are either gel or antiseptic based
- A lot of people get influenced by advertisements, and the most popular medium is television
The conclusion for X can be written as: (1) the main market is urban families earning ₹10,000-30,000; (2) make a gel or antiseptic toothpaste; (3) price it so the family’s monthly spend stays near ₹104; (4) stress quality and standardised marking; (5) advertise mainly on television and in newspapers.
7 Chapter 5 tools on the same survey: median, mode and ogives
The book finds only the mean. Median and mode on such data are also asked in exams, so the same data are solved further below.
Cumulative frequencies: 20, 60, 90, 100; → median class 10000-20000 (first cf above 50 is 60)
Median ₹17,500
Modal class 10000-20000 (, , )
Mode ₹16,666.67
Interpretation: half the families earn less than ₹17,500 and the most common income is about ₹16,667; the mean (₹18,000) is slightly higher because a few families earn much more.

- “Less than” ogive points: (10000, 20), (20000, 60), (30000, 90), (40000, 100), plotted at each class’s upper limit
- “More than” ogive points: (0, 100), (10000, 80), (20000, 40), (30000, 10), plotted at each class’s lower limit
- The point where they cross gives the median on the x-axis: ₹17,500, exactly the formula’s answer
Cumulative frequencies: 5, 25, 65, 95, 100; → median class 80-120
Median ₹105
Modal class 80-120: mode ₹106.67
Interpretation: mean (₹104), median (₹105) and mode (₹106.67) are nearly equal; the spending distribution is nearly symmetric.
Before the median, the data must be in order and the cumulative frequencies built. The cf used is that of the class before the median class, not the median class’s own.
8 Appendix A: key statistical terms
The book ends with a glossary of the whole book’s terms. These are the terms you need most while writing a project and in the viva.
Population: all the individuals/units for whom the information has to be sought.
Census method: a method of data collection which requires that observations are taken on all the individuals in a population.
Sample survey method: a method where observations are obtained on a representative set of individuals (the sample) selected from the population.
Random sampling: a method of sampling in which the representative set of informants is selected in a way that every individual is given an equal chance of being selected as an informant.
Assumed mean: an approximate value in order to simplify calculation.
Class midpoint: the middle value of a class, the representative value of the observations in it; equal to (upper class limit + lower class limit) ÷ 2.
| Term | Meaning (Appendix A) |
|---|---|
| Informant | Individual/unit from whom the desired information is obtained |
| Enumerator | A person who collects the data |
| Sampling error | Numerical difference between the estimate from the sample and the true value of the parameter in the population |
| Non-sampling error | Arises in data collection due to (i) sampling bias (ii) non-response (iii) error in data acquisition |
| Variable | A quantity measuring an attribute (height, weight, number) that can take different values |
| Discrete / continuous variable | Takes only certain values (finite “jumps”) / can take any numerical value |
| Attribute | A qualitative characteristic; it cannot be measured |
| Frequency distribution | Classification of a quantitative variable showing how its values are distributed in classes with their frequencies |
| Relative frequency | Frequency of a class as a proportion or percentage of total frequency |
| Inclusive / exclusive method | An observation equal to a class limit is put in that class / in the class above or below |
| Tally marking | Counting observations in a class using tally (/) marks, grouped in fives |
| Time series | Data in chronological order, or two-variable data where one variable is time |
| Cyclicity / seasonality | Periodicity in data with a period of more than one year / less than one year |
| Bimodal / multi-modal distribution | Two modes / more than two modes |
| Range | Difference between the maximum and the minimum values of a variable |
| Decile / percentile | Partition values dividing data into 10 / 100 equal parts (99 percentiles) |
| Weighted average | Average calculated by giving different data points different weights |
| Analysis / policy | Understanding an economic problem in terms of its causes / the measure to solve it |
9 Appendix B: table of two-digit random numbers
The book ends with a table of two-digit random numbers. It is used to choose a random sample, so that every unit gets an equal chance of selection and the investigator’s bias does not enter.
Step 1: number all 100 households from 01 to 100 (take 00 for 100).
Step 2: read two digits at a time from the first row of the table: 03, 47, 43, 73, 86
Step 3: the households with these numbers form the sample: households 3, 47, 43, 73 and 86
If a number repeats, skip it and take the next one.
10 Formulas, differences and common mistakes in one place
| Basis | Census method | Sample method |
|---|---|---|
| Information from | Every unit of the population | A representative sample |
| Time, money, labour | More | Less |
| Error | No sampling error | Sampling error possible |
| The book’s example | Female literacy/soap consumption: every household | Toothpaste survey: 100 households |
✓ Do this in a project
- Write the objective in one sentence first
- Write an observation under every table
- Give the unit with every number (₹, households, persons)
- List every secondary source in the bibliography
✗ Never do this
- A pie diagram of multiple-response data (total above 100)
- A sample unrelated to the objective (only low-income families for a car study)
- Copying someone else’s project (original work is required)
- A conclusion without data
- The objective of the study should be clearly identified
- The population and sample have to be chosen carefully
- The objective of the survey indicates the type of data to be used
- A questionnaire/interview schedule is prepared
- Collected data can be analysed by using various statistical tools
- Results are interpreted to draw meaningful conclusions
- Toothpaste survey: 100 households, mean income ₹18,000, mean toothpaste spend ₹104, median income ₹17,500
- CBSE project: 20 marks = 3 + 6 + 3 + 8 (viva-voce 8)
- Can I write all seven steps of a project in order?
- Can I give the target groups for cars, soap and drinking water?
- Can I state when secondary data are used?
- Can I redo the ₹18,000 and ₹104 means by the step-deviation method?
- Can I find pie-diagram angles and the median from the two ogives?